I built a live digit recogniser that runs in your browser. Point a camera at a handwritten number and a convolutional network from 1998 tells you what it is, in about half a millisecond, without sending a single pixel anywhere.
The model has 61,706 trainable numbers. That is small enough that you can account for every one of them, which is what makes it worth studying. A modern image model has hundreds of millions and you take the architecture on faith. Here you do not have to.
This post builds the whole thing from the bytes up. What MNIST actually is as a file. What a convolution does to a grid of numbers, and where its weights live. How the 61,706 are distributed across layers. What the two changes I made to the 1998 design are worth when you measure them instead of repeating folklore. And why the model gets checked a second time after it leaves PyTorch.
A mental model that survives contact with code. Not "filters detect edges" but the specific arithmetic: which numbers get multiplied by which, how many there are, and why a convolution needs 156 parameters where a dense layer would need 3,692,640 for the identical input and output.
The honest version of a common claim. Swapping the 1998 activations and pooling for modern ones is supposed to be a clear win. I ran it four ways across four random seeds. The result is more interesting than the folklore.
A pipeline you can run. Training takes 91 seconds. Export is checked against all 10,000 test images before it ships. Every number in this post came from that code on my machine.
Sixty Thousand Pictures Behind a Sixteen-Byte Header
MNIST is a set of 70,000 images of handwritten digits, 60,000 for training and 10,000 held back for testing. Everyone uses torchvision.datasets.MNIST and never looks inside. Look inside once, because the format explains the model.
The data ships in a format called IDX, which is about as simple as a binary format gets. Here are the real first sixteen bytes of the training images file, in hexadecimal, where each pair of characters is one byte:
00 00 08 03   00 00 ea 60   00 00 00 1c   00 00 00 1c
└──┬──┘ │ │   └─────┬────┘   └─────┬────┘   └─────┬────┘
   │    │ │        60000            28            28
   │    │ └── 3 dimensions
   │    └──── 0x08 means "every value is one unsigned byte"
   └───────── two zero bytes, always
That is the entire header. Two padding bytes, a type code, a count of dimensions, then one four-byte number per dimension. After byte 16, the pixels start and never stop.
Two things are worth slowing down on.
The numbers are big-endian. A four-byte integer can be written most significant byte first or least significant byte first, and the two conventions disagree completely. Reading 00 00 ea 60 the intended way gives 60,000. Reading the same four bytes backwards gives 1,625,948,160. There is nothing in the file that tells you which convention applies. You have to know, which is why a format always needs a spec alongside it.
If you want to check the arithmetic by hand, each hex digit is a power of 16, counting from the right, and the letters run a=10 through f=15:
$$ \texttt{ea60} = 14 \times 16^3 + 10 \times 16^2 + 6 \times 16^1 + 0 \times 16^0 = 57344 + 2560 + 96 = 60000 $$
Grouping by byte instead of by digit is the same sum rearranged. One byte is two hex digits, so each step left multiplies by $16^2 = 256$: ea is 234, 60 is 96, and $234 \times 256 + 96 = 60000$. Bytes are the natural unit when you are reading a file, so that is usually the easier grouping.
The file size proves the parse. The header is 16 bytes and each image is $28 \times 28 = 784$ bytes, so the file should be exactly $16 + 60000 \times 784 = 47{,}040{,}016$ bytes. It is. Nothing is missing, nothing is left over, and no image is misaligned. That check costs one line and catches an entire family of bugs where an off-by-one in the header offset shifts every image by a few pixels.
The whole reader is seven lines:
import gzip
import struct
import numpy as np

def read_idx(path):
    """IDX: 2 zero bytes, 1 type byte, 1 byte of dimension count,
    then each dimension as a 4-byte big-endian int, then the data."""
    data = gzip.open(path).read()
    ndim = data[3]
    shape = struct.unpack(">" + "I" * ndim, data[4:4 + 4 * ndim])
    return np.frombuffer(data, dtype=np.uint8, offset=4 + 4 * ndim).reshape(shape)
In struct.unpack, the > means big-endian and each I means one four-byte unsigned integer, so ">III" reads three of them. np.frombuffer wraps the existing bytes as an array without copying them, which is why the resulting array is read-only. If you have ever seen PyTorch warn that "the given NumPy array is not writable" while loading MNIST, that warning traces back to exactly this line.
One habit worth keeping: verify the download with a checksum, a short fingerprint computed from the file's contents. A half-finished download still opens without error and still parses, it just quietly contains less data than you think. The four MNIST files have published MD5 checksums, and I confirmed the ones in my copy match the values torchvision ships in its own loader:
train-images-idx3-ubyte.gz       f68b3c2dcbeaaa9fbdd348bbdeb94873
train-labels-idx1-ubyte.gz       d53e105ee54ea40749a09fcbcd1e9432
t10k-images-idx3-ubyte.gz        9fb629c4189551a2d022fa330f9573f3
t10k-labels-idx1-ubyte.gz        ec29112dd5afa0611ce80d1b7f02629c
A checksum you compute from your own download only proves the file will not change later. It becomes meaningful when the expected value comes from somewhere else, so two independent sources have to agree. MD5 is the right tool for catching a truncated download and the wrong tool for catching deliberate tampering, because it is possible to construct two different files with the same MD5. For MNIST that is fine, and it is what the published values use.
The Three Numbers That Define the Format
Parse the file and you can measure what an MNIST digit actually looks like. Three statistics matter more than the rest, because the model will come to depend on all three without ever being told about them.
Ink is white, background is black. Pixel values run 0 to 255, and 80.9% of all pixels in the training set are exactly 0. A photograph of a digit on paper is the opposite: dark ink on a light page. Any real-world image has to be inverted before the model sees it.
The digit always fits a 20 by 20 box. I measured the longest side of the ink's bounding box across 5,000 training images. The median is 20 pixels. So is the 5th percentile, and so is the 95th. Every single one is exactly 20, because MNIST was constructed that way: the original digit was scaled so its longest side hit 20 pixels, then placed in a 28 by 28 field. The 4-pixel margin is not decoration, it is headroom for the next statistic.
The digit is centred by centre of mass at (14, 14). Across those same images the mean centre of mass sits at row 13.99, column 14.00. Centre of mass means the average position of the ink weighted by brightness, not the centre of the bounding box. The two differ for any digit whose weight is unevenly distributed. A 7 carries a heavy horizontal bar at the top, so centring it by mass pushes the glyph slightly lower in the frame than centring it by its box would.
The classes are also close to balanced, from 5,421 examples of digit 5 to 6,742 of digit 1, so there is no need to reweight anything during training.
Those three facts are the contract. The model will only ever see images that satisfy them, so it will only ever be reliable on images that satisfy them. Most of the work in the browser tool at the end of this post is spent forcing camera frames to comply. A model that scores 99% on MNIST and then fails on real handwriting has usually not been let down by its weights. Nobody enforced the contract at inference time.
Where Are the Weights?
Now the part that actually blocks people, and the reason I wrote this post the way I did.
If you learned neural networks from the standard diagram, you have a specific picture in your head. Circles in columns. Every circle in one column connected to every circle in the next. A weight sitting on each connection, and training nudging those weights. Counting parameters is easy: multiply the two column sizes, add one bias per output.
Then convolution arrives and the explanation changes vocabulary entirely. Filters, kernels, feature maps, sliding windows. The picture of neurons and connections disappears, and nobody says whether it was wrong or just hidden. So the honest question is: in that first picture, where are a convolution's weights?
They are exactly where you think. On the connections. A convolution is the same picture with two restrictions added.
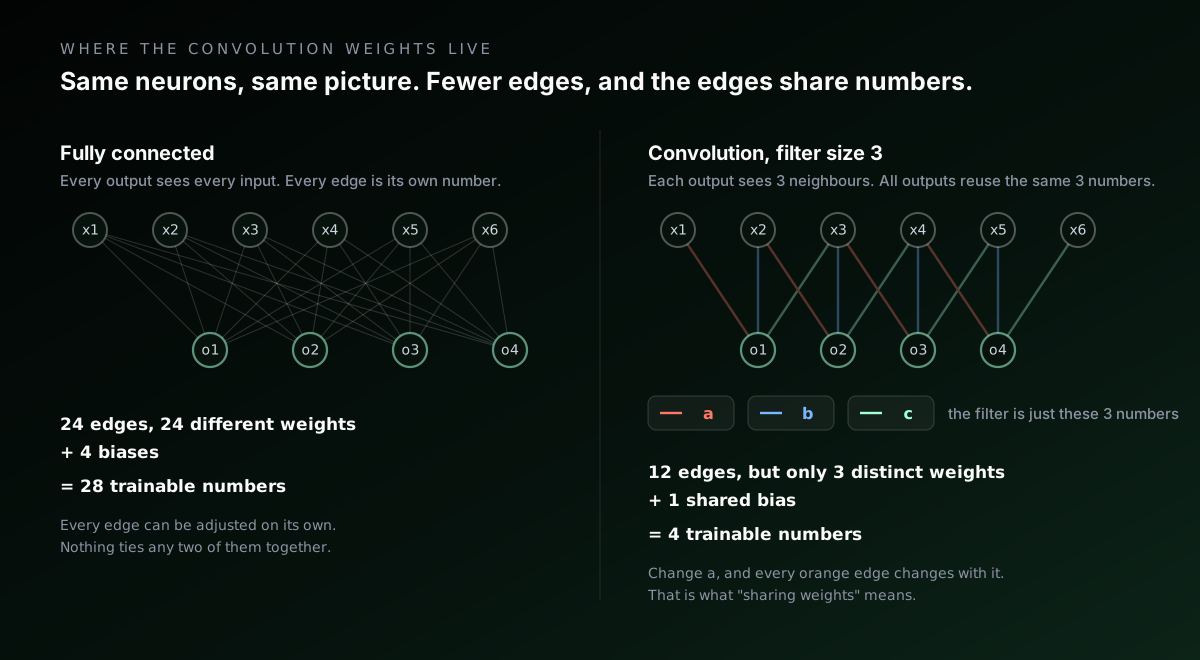
Take six inputs and four outputs. Fully connected, that is $6 \times 4 = 24$ connections, each with its own weight, plus 4 biases, so 28 trainable numbers.
Now add restriction one: each output only connects to a few neighbouring inputs. With a filter size of 3, output o1 reaches x1, x2, x3, output o2 reaches x2, x3, x4, and so on. The connections that are missing are not weights set to zero and then trained, they simply do not exist. Twelve connections instead of twenty four.
Add restriction two: every output reuses the same weights. Call them $a$, $b$ and $c$. Then:
$$ \begin{aligned} o_1 &= a x_1 + b x_2 + c x_3 + \text{bias} \\ o_2 &= a x_2 + b x_3 + c x_4 + \text{bias} \\ o_3 &= a x_3 + b x_4 + c x_5 + \text{bias} \\ o_4 &= a x_4 + b x_5 + c x_6 + \text{bias} \end{aligned} $$
Same $a$, $b$, $c$ in every row, just applied one position further along. Twelve connections exist, but there are only three distinct numbers among them, plus one shared bias. Four trainable numbers, not twenty eight.
That is the rule that makes parameter counting work: a trainable parameter is a distinct weight value, not a connection. When training adjusts $a$, all four connections carrying $a$ change together, because they are all one number stored in one place.
And "the filter" is nothing more exotic than the list of those shared weights. Saying "a filter of size 3 slides across the input" and saying "every output neuron connects to its own three neighbours using the same three weights" describe the same object. One phrasing emphasises the motion, the other the wiring. The motion is the metaphor. The wiring is what is in memory.
If that still feels like a story rather than a fact, it is checkable. Write the convolution out as a dense weight matrix, one row per output neuron and one column per input, and multiply. For a 4 by 4 input and a 3 by 3 filter producing a 2 by 2 output, that matrix has 64 entries, of which 36 are non-zero and only 9 are distinct:
      x1  x2  x3  x4  x5  x6  x7  x8  x9 x10 x11 x12 x13 x14 x15 x16
o1:    a   b   c   .   d   e   f   .   g   h   i   .   .   .   .   .
o2:    .   a   b   c   .   d   e   f   .   g   h   i   .   .   .   .
o3:    .   .   .   .   a   b   c   .   d   e   f   .   g   h   i   .
o4:    .   .   .   .   .   a   b   c   .   d   e   f   .   g   h   i
I built that matrix explicitly and multiplied it by a random input. It matches F.conv2d on the same input to within floating point error. A convolution is a dense layer whose weight matrix is mostly zeros, with the surviving entries reused across every row. Nothing more mysterious than that.
One Filter, Many Positions
With the wiring settled, the mechanics are arithmetic. At each position the filter covers a patch of the input, multiplies each covered number by its corresponding weight, adds the results, adds the bias, and writes one number to the output.
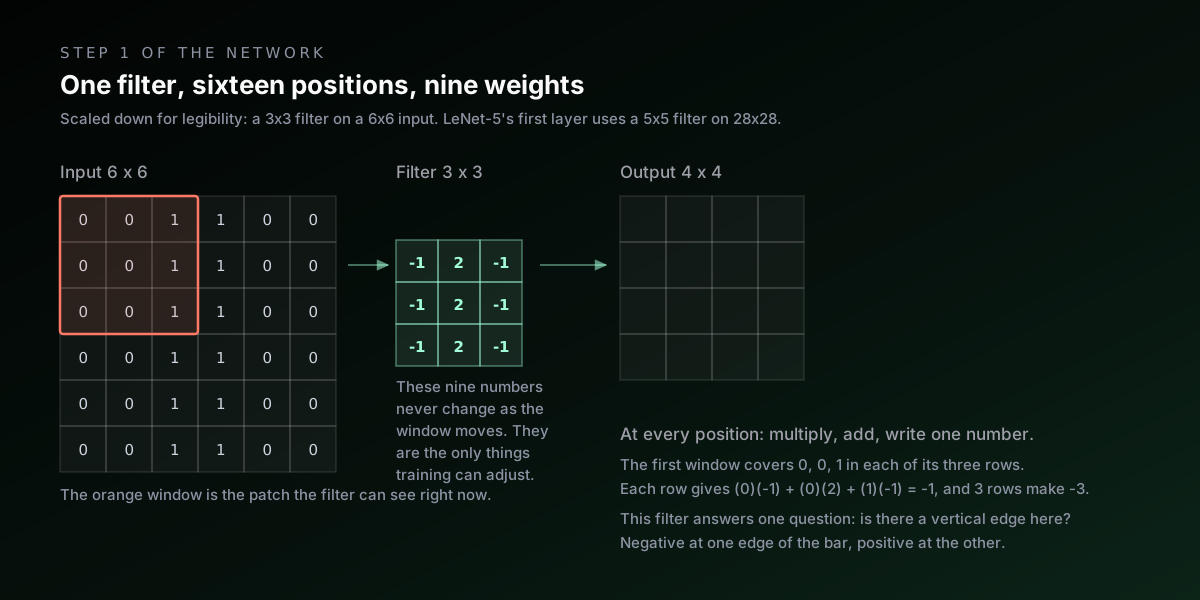
The example in that diagram uses an input with a vertical bar of 1s down the middle of a field of 0s, and a filter whose every row is $[-1, 2, -1]$. Work one position by hand. The leftmost window covers columns 0, 1, 2, which read $0, 0, 1$ in every row. One row contributes $(0)(-1) + (0)(2) + (1)(-1) = -1$, and there are three rows, so the output is $-3$. Slide one step right and the patch becomes $0, 1, 1$, giving $(0)(-1) + (1)(2) + (1)(-1) = +1$ per row, so $+3$.
The full output is $-3, +3, +3, -3$ in every row. The filter is strongly negative at the bar's left edge, strongly positive at its right edge, and would be zero anywhere the input is flat. It answers one narrow question at every location at once: how sharply does brightness change from left to right here?
Two details that trip people up.
The output is smaller than the input, unless you pad. A 3 by 3 filter on a 6 by 6 input only has 4 valid positions per axis, because the filter has to fit entirely inside. In general a $k \times k$ filter turns an $n \times n$ input into $(n - k + 1)^2$ outputs. LeNet-5's first layer uses a 5 by 5 filter on a 28 by 28 image, which would give 24 by 24. I pad the input with 2 pixels of zeros on every side so the output stays 28 by 28, which is the modern convention and keeps the arithmetic tidy.
Frameworks do not flip the filter. Textbook convolution reverses the filter before multiplying. PyTorch's conv2d, like almost every deep learning framework, skips the flip and computes what mathematicians call cross-correlation. Since the weights are learned anyway, the network simply learns the flipped version if that is what it needs, and nobody notices. It matters only if you are hand-building a filter and expecting a specific sign.
Stacking Filters, and What a Channel Is
One filter produces one output grid. That grid is called a feature map, and it records how strongly that one filter responded at every location.
Detecting only vertical edges is not much of a vision system, so a layer uses several filters. Six filters produce six feature maps, each from its own independent set of weights. Nothing is shared between filters.
Now the input to the next layer is six grids rather than one. This is where the counting gets its one genuinely new rule: a filter must have one slice for every input grid. If a layer receives 6 feature maps and uses 5 by 5 filters, then each of its filters is a stack of 6 separate 5 by 5 grids of weights, a total of 150 numbers. Each slice is applied to its matching input grid, and the results are added together into a single output grid.
So the general formula is:
$$ \text{params} = \underbrace{F}_{\text{filters}} \times \Big( \underbrace{C}_{\text{input maps}} \times k \times k + \underbrace{1}_{\text{bias}} \Big) $$
More filters means more output maps. More input maps means thicker filters and more numbers added into each output. That single formula accounts for every convolutional parameter in the network.
Pooling, or Discarding Three Quarters on Purpose
Between convolutions sits a pooling layer, which shrinks each feature map by summarising small neighbourhoods. With 2 by 2 max pooling, every non-overlapping 2 by 2 block is replaced by its largest value, so a 28 by 28 map becomes 14 by 14 and three quarters of the numbers are gone.
Pooling has no weights at all. It is a fixed rule, so there is nothing for training to adjust.
It buys two things. The obvious one is cost: everything downstream operates on a quarter as many numbers. The subtler one is that it makes the network slightly indifferent to exact position. If a stroke shifts by one pixel, the maximum within its block is often unchanged, so the summary is unchanged. For reading handwriting, where nobody writes the same 4 twice, a little positional indifference is exactly what you want.
Shrinking the grid also widens what each later unit can see. The receptive field of a unit is the region of the original image that can influence it. I measured it by backpropagating a one into a single unit and checking which input pixels received gradient:
| After | Output shape | Receptive field |
|---|---|---|
| C1 conv | 6 x 28 x 28 | 5 x 5 |
| S2 pool | 6 x 14 x 14 | 6 x 6 |
| C3 conv | 16 x 10 x 10 | 14 x 14 |
| S4 pool | 16 x 5 x 5 | 16 x 16 |
A unit in the first layer sees a 5 by 5 patch, about the size of a stroke fragment. By the second convolution a unit sees 14 by 14, half the image, enough for a loop or the junction of a 4. The network builds from strokes to parts without anyone specifying what a stroke or a part is.
The Full Architecture, Layer by Layer
Here is the whole network, with the tensor shape at every stage and the parameters each stage owns.
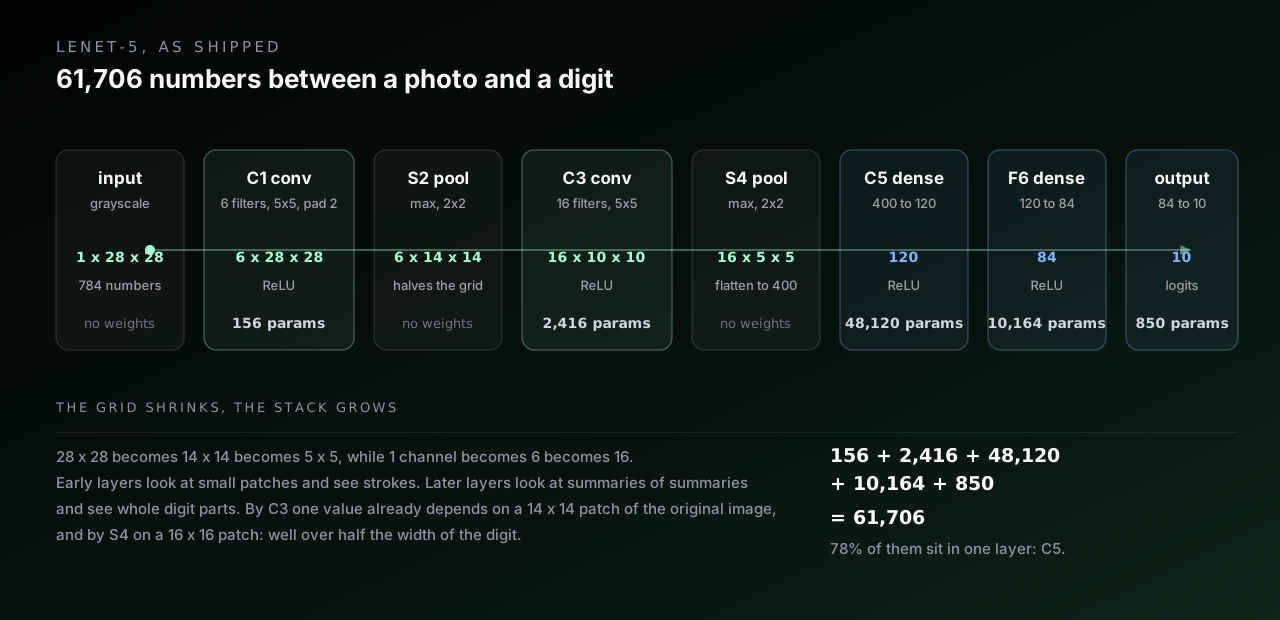
In PyTorch the definition is short enough to read in one pass:
import torch.nn as nn

class LeNet5(nn.Module):
    def __init__(self, num_classes: int = 10):
        super().__init__()
        self.features = nn.Sequential(
            nn.Conv2d(1, 6, kernel_size=5, padding=2),   # 1 x 28 x 28 -> 6 x 28 x 28
            nn.ReLU(inplace=True),
            nn.MaxPool2d(2),                             #            -> 6 x 14 x 14
            nn.Conv2d(6, 16, kernel_size=5),             #            -> 16 x 10 x 10
            nn.ReLU(inplace=True),
            nn.MaxPool2d(2),                             #            -> 16 x 5 x 5
        )
        self.classifier = nn.Sequential(
            nn.Flatten(),                                #            -> 400
            nn.Linear(16 * 5 * 5, 120),
            nn.ReLU(inplace=True),
            nn.Linear(120, 84),
            nn.ReLU(inplace=True),
            nn.Linear(84, num_classes),                  #            -> 10
        )

    def forward(self, x):
        return self.classifier(self.features(x))
The last layer returns ten raw scores called logits, one per digit. They are not probabilities and can be negative. Turning them into probabilities means exponentiating each and dividing by the total, which is the softmax function. I deliberately leave softmax out of the model, for a reason that matters at export time and that I will come back to.
Counting the 61,706
Apply the formula layer by layer.
| Layer | Shape in | Shape out | Calculation | Parameters |
|---|---|---|---|---|
| C1 conv | 1 x 28 x 28 | 6 x 28 x 28 | 6 x (1 x 5 x 5 + 1) | 156 |
| S2 pool | 6 x 28 x 28 | 6 x 14 x 14 | fixed rule | 0 |
| C3 conv | 6 x 14 x 14 | 16 x 10 x 10 | 16 x (6 x 5 x 5 + 1) | 2,416 |
| S4 pool | 16 x 10 x 10 | 16 x 5 x 5 | fixed rule | 0 |
| C5 dense | 400 | 120 | 120 x (400 + 1) | 48,120 |
| F6 dense | 120 | 84 | 84 x (120 + 1) | 10,164 |
| Output | 84 | 10 | 10 x (84 + 1) | 850 |
| Total | 61,706 |
Two things in that table are worth sitting with.
The convolutions are almost free, and do almost all the work. C1 and C3 together hold 2,572 parameters, 4.2% of the model. C5 alone holds 78%. But counting multiply-accumulate operations for a single image instead of parameters reverses the picture completely:
| Layer | Multiply-accumulates | Share of compute | Share of parameters |
|---|---|---|---|
| C1 conv | 117,600 | 28.2% | 0.3% |
| C3 conv | 240,000 | 57.6% | 3.9% |
| C5 dense | 48,000 | 11.5% | 78.0% |
| F6 dense | 10,080 | 2.4% | 16.5% |
| Output | 840 | 0.2% | 1.4% |
The two convolutions are 4.2% of the parameters and 85.9% of the arithmetic. That is weight sharing stated as a ratio: the same 156 numbers get reused across 784 positions, so a tiny amount of memory drives a large amount of computation. The dense layers are the opposite, a large amount of memory used exactly once each.
Weight sharing is doing enormous work in C1. That layer maps 784 input values to $6 \times 28 \times 28 = 4{,}704$ output values. Count it three ways:
| How you count C1 | Number |
|---|---|
| A fully connected layer between the same two sets of neurons | 3,692,640 |
| Connections that actually exist in the convolution | 117,600 |
| Distinct trainable numbers in the convolution | 156 |
Same inputs, same outputs, 23,671 times fewer parameters. That ratio is the entire reason convolutional networks work on images with modest data and modest hardware. A fully connected first layer would have to learn what a stroke looks like separately at every one of 784 positions. Nothing it learned in the top left corner would transfer to the bottom right. The convolution learns it once and applies it everywhere.
What I Changed From 1998
The architecture above is LeNet-5 as published, with the original layer shapes and therefore the original parameter count, but two substitutions that are now standard.
Activations: tanh became ReLU. An activation function is the nonlinearity applied after each layer, and without one a stack of layers collapses into a single linear layer no matter how deep it is. The 1998 network used $\tanh$, which squashes any input into the range $[-1, 1]$. The modern default is ReLU, the rectified linear unit, which is just $\max(0, x)$: negatives become zero and positives pass through unchanged.
The textbook argument for ReLU is gradient flow. $\tanh$ flattens out at both ends, so a unit with a large input has a derivative near zero and receives almost no gradient. Stack enough of those and the signal reaching the early layers vanishes. ReLU's derivative is exactly 1 for every positive input, so gradient passes through undiminished however deep the stack gets.
Pooling: average became max. The original paper used average pooling with a trainable coefficient per map. I use plain max pooling, which keeps the strongest response in each block rather than blending the block together. The intuition is that for detecting whether a feature is present, the peak response carries the signal and averaging it with three neighbours dilutes it.
Neither change affects the parameter count, since activations and pooling rules have no weights. Both are repeated constantly as obvious improvements. So I measured them.
What the Change Was Actually Worth
I trained all four combinations under identical conditions: same initialisation seed, same data order, same optimiser, same eight epochs. Then I repeated the whole thing across four different seeds, because a single run cannot tell you whether a gap is real or just where the random number generator happened to land.
| Variant | seed 1998 | seed 7 | seed 42 | seed 2024 | Mean |
|---|---|---|---|---|---|
| 1998 original: tanh + average pool | 98.92% | 98.80% | 99.08% | 98.93% | 98.93% |
| tanh + max pool | 98.85% | 98.99% | 98.93% | 98.81% | 98.89% |
| ReLU + average pool | 98.96% | 98.96% | 99.00% | 98.89% | 98.95% |
| shipped: ReLU + max pool | 99.05% | 98.89% | 98.99% | 98.95% | 98.97% |
The modern pair averages 98.97% and the 1998 pair averages 98.93%. That is a gap of 0.037 percentage points, which on 10,000 test images is about four images.
Now compare that to how much a single variant moves when you change nothing but the seed. The 1998 configuration ranges from 98.80% to 99.08% across its four runs, a spread of 0.28 points. The gap between the best and worst variant is roughly seven times smaller than the variation within one variant.
Every one of the sixteen runs lands between 98.80% and 99.08%. The highest single score in the entire experiment, 99.08%, belongs to the 1998 original. The shipped configuration beats the original on three seeds out of four and loses on the fourth. There is no effect here to report.
The theoretical argument for ReLU is about deep networks. LeNet-5 is five layers deep. Vanishing gradients through $\tanh$ are a real problem at twenty layers and a mild one at five, so the thing ReLU is best at barely gets to matter here. Adam, the optimiser, adapts its step size per parameter and papers over a good deal of what the activation choice would otherwise cost. The 1998 design was not holding anything back on this problem.
I kept ReLU and max pooling anyway, for reasons that are honest but have nothing to do with accuracy. They are the modern default, so the code reads as familiar. ReLU also exports to a cheaper operation for browser inference. What I will not claim is that they bought accuracy, because measured properly, on this problem, they did not.
Training It
The training script is ordinary, which is the point. The interesting decisions are in the data and the architecture, not the loop.
train_tf = transforms.Compose([
    transforms.RandomAffine(degrees=10, translate=(0.1, 0.1), scale=(0.9, 1.1)),
    transforms.ToTensor(),
    transforms.Normalize((0.1307,), (0.3081,)),
])
Three things happen to every training image.
Mild affine jitter. Each image is randomly rotated up to 10 degrees, shifted up to 10%, and scaled between 0.9 and 1.1. This is data augmentation: making slightly altered copies so the model sees more variety than the dataset literally contains. The amounts are deliberately small, because the preprocessing in the browser already centres and scales the digit the way MNIST does. The variation left to cover is the wobble in how somebody writes, not large transformations that preprocessing will remove anyway.
Conversion to floats in $[0, 1]$. Pixels are stored as bytes to keep the dataset at 47 MB, and converted only at training time.
Normalisation. Subtract 0.1307 and divide by 0.3081, the mean and standard deviation of MNIST pixel values. This centres the inputs near zero with a spread near one, which is the range optimisers are tuned for. Those two constants have to be applied identically at inference, and getting them wrong there is a classic silent failure: the model still runs, still outputs confident answers, and is quietly worse.
The loop itself is Adam at a learning rate of 0.001, a batch size of 128, cross-entropy loss, and a cosine schedule that anneals the learning rate towards zero across the run. After each epoch the model is evaluated on the 10,000 test images and the best one is saved.
device: mps
parameters: 61,706
epoch  1/15  train_loss 0.5458  test_loss 0.0953  test_acc 96.91%  11.0s
epoch  5/15  train_loss 0.0866  test_loss 0.0402  test_acc 98.58%   5.7s
epoch 10/15  train_loss 0.0546  test_loss 0.0299  test_acc 99.03%   5.7s
epoch 14/15  train_loss 0.0436  test_loss 0.0205  test_acc 99.30%   5.8s
epoch 15/15  train_loss 0.0419  test_loss 0.0205  test_acc 99.27%   5.8s

best test accuracy: 99.30%  (90.9s total)
Ninety one seconds on an M4's GPU through PyTorch's mps backend, for 99.30% on data the model never trained on. It is worth pausing on how little that costs now. The 1998 paper's experiments took days.
One caveat about that number, since this post is partly about not overclaiming. The 10,000 test images were used to pick which epoch to keep. That makes 99.30% very slightly optimistic as an estimate of performance on genuinely unseen data, because the test set influenced one decision. The clean version uses a third split for model selection. At this scale the effect is small, but it is the kind of thing worth saying out loud rather than discovering in the comments.
Exporting to ONNX, and Why I Check It Afterwards
The browser cannot run PyTorch, so the trained model is converted to ONNX, a portable format that describes a network as a graph of standard operations. Lots of runtimes can read it, including one that runs in a browser tab.
torch.onnx.export(
    model,
    (torch.zeros(1, 1, 28, 28),),
    "lenet5.onnx",
    input_names=["input"],
    output_names=["logits"],
    dynamic_axes={"input": {0: "batch"}, "logits": {0: "batch"}},
    opset_version=13,
)
The result is a 243 KB file. Smaller than most of the images on this page.
Now the part most tutorials skip. Export is a translation between two systems with different internal conventions, and translations can change behaviour: operations get fused, a padding convention is interpreted differently, a dtype is silently narrowed. The failure mode is nasty precisely because it is quiet. The model looks fine in Python, and misclassifies in the browser, and nothing anywhere reports an error.
So the export script runs both models over all 10,000 test images and compares their raw outputs:
torch_logits = model(images).numpy()
onnx_logits = session.run(["logits"], {"input": images.numpy()})[0]

max_abs_diff = max(max_abs_diff, float(np.abs(torch_logits - onnx_logits).max()))
label_mismatches += int((torch_logits.argmax(1) != onnx_logits.argmax(1)).sum())
parity check
samples 10000
max abs logit diff 1.335e-05 (tolerance 1e-04)
prediction mismatches 0
pytorch accuracy 99.30%
onnx accuracy 99.30%
result PASSZero disagreements out of ten thousand, and the largest difference between any two corresponding logits is 1.3 in the fifth decimal place, which is ordinary floating point drift from operations being reordered. If either check failed the script exits non-zero and the file does not ship.
This is also where leaving softmax out of the model pays off. Comparing logits compares the model's actual output. Softmax squashes everything into $[0, 1]$ and compresses differences, so two models that genuinely disagree can look similar after it. Comparing before the squashing makes the check strictly more sensitive. The browser applies softmax afterwards, where a discrepancy cannot hide.
Writing the accuracy into a small JSON file next to the model is a related habit. The page reads its "99.30%" from that file rather than from hardcoded text, so the number on screen always belongs to the model actually being served. Retrain, and the page updates itself or it does not change at all. It cannot drift into being confidently wrong.
What the Browser Tool Actually Does
The tool is the same 61,706 numbers, running in a worker thread through ONNX Runtime Web. Two parts are worth describing, because between them they are most of the difficulty.
Preprocessing is where accuracy is won or lost. The model only ever saw images obeying the three statistics from earlier. A camera frame obeys none of them. So every frame goes through five steps before a single weight is touched.
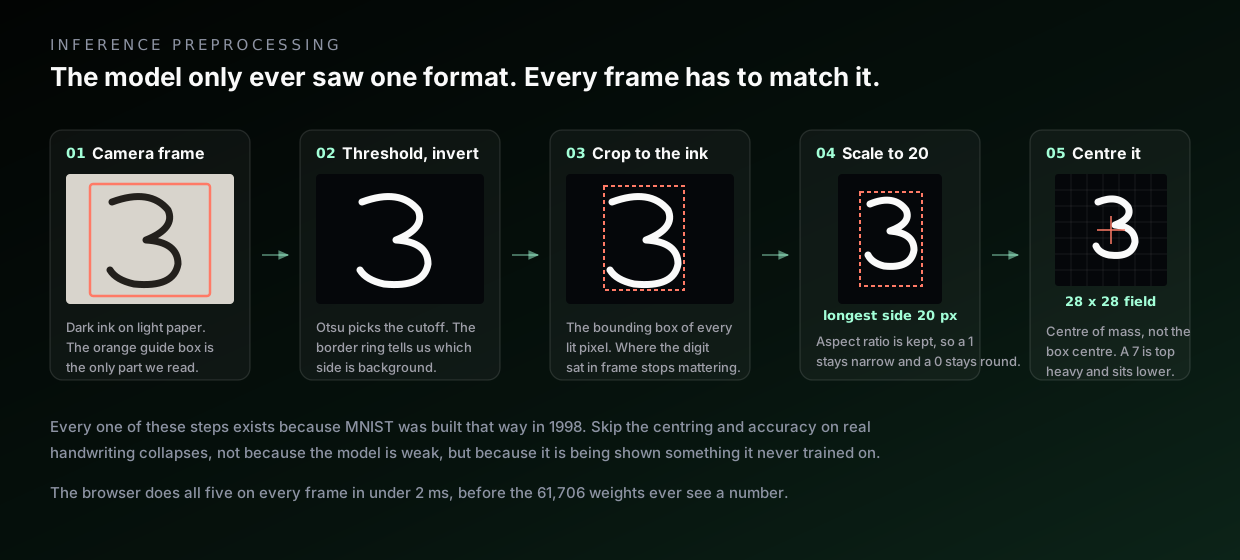
The frame is cropped to the guide box. A threshold separates ink from paper, chosen automatically by Otsu's method, which picks the cutoff that best splits the pixel histogram into two groups. Polarity is decided by looking at the border ring of the crop, which is background by construction, so if the border is the bright side then the ink is dark and the image gets inverted. The image is cropped tight to the ink's bounding box, which removes any dependence on where the digit sat in frame. It is scaled so its longest side is 20 pixels, preserving aspect ratio so a 1 stays narrow and a 0 stays round. Finally it is placed into a 28 by 28 field positioned so its centre of mass lands at the centre.
Two details in that list are worth more than they look, because both were bugs before they were features.
The first is that the ink has to be rescaled by its own peak, not by the full 0 to 255 range. A camera never sees pure black ink on a pure white page: marker reads around 40 to 70, and cream paper closer to 200 than 255. Scale against the theoretical range and the stroke arrives at roughly half brightness, while every MNIST digit has a fully saturated core. The network is then being asked about something it has never seen. Measured on a synthetic page, the stroke reached the model at a peak of 142 out of 255 instead of 255, and confidence fell with the light. Rescaling by the ink's own 99th percentile, rather than its maximum so one specular highlight cannot set the range, puts it back at 255.
The second is that Otsu finds the strongest boundary in the frame, which is not always the one you want. Hold a sheet of paper that does not fill the guide box and the strongest boundary is desk against page, not ink against page. What comes back is the sheet itself, a solid block the network reads as some bold, blobby digit, which is the failure you see as a confident wrong answer that ignores your writing. The tell is geometric: a stroke never fills its own bounding box, and a surface nearly does. Measuring all ten digits at three stroke widths, the worst genuine case was a thick 1, whose box is a narrow slab filled to 0.74, over an area of 0.11 of the frame. A page sits near 0.89 over 0.21 or more. When both numbers say surface, the preprocessor looks again inside that region, where the only two levels left are paper and ink.
Those are not arbitrary choices. They are the MNIST construction procedure, reimplemented in JavaScript, because the only way to make a model work on new data is to hand it something shaped like its training data.
The runtime sits in a worker. A worker is a separate thread, so inference never blocks the camera loop or the interface. Each frame posts a 784-number array across, gets back ten probabilities, and the main thread stays free to draw. Inference takes 0.5 to 1.0 ms and preprocessing 1.6 to 1.9 ms, so the budget is dominated by getting the image into shape rather than by the network.
Two small behaviours came out of testing rather than design. The first is that drawing updates arriving while an inference is in flight were being dropped, so the readout could describe a stroke you had already finished changing. The fix is to remember that a newer version exists and re-run as soon as the worker frees up. The second involves the smoothing that steadies the live camera reading, an exponential average over recent frames. That averaging is actively wrong for the drawing canvas, where each update is a genuinely different shape rather than a noisy repeat of the same one. It now smooths the camera only. Both bugs looked like model problems and were not.
Where This Leaves the Model
LeNet-5 at 99.30% on MNIST is a solved problem and has been for a long time. The reason to build it is not the score, it is that at 61,706 parameters every design decision is still legible. You can count the weights, measure the receptive field, verify by direct computation that a convolution is a weight-shared dense layer, and test whether a change you made was worth anything. None of those are available to you on a model with 400 million parameters, and the intuitions you build here are the ones you carry there.
The honest summary of what the investigation turned up is this. The architecture does the heavy lifting, and weight sharing is where its leverage comes from: 156 parameters doing a job that would otherwise take 3.7 million. The modernisations I made on top of the 1998 design are defensible on other grounds but did not buy accuracy, and I only know that because I measured across seeds instead of running once. The preprocessing is not a detail around the edges of the model, it is half the system, and it is the half that decides whether the thing works on real handwriting. And the export needs checking, because the one failure mode that will genuinely cost you a weekend is the one that reports success at every step.
The tool is here, and the training, export and ablation scripts are in the same folder as the page itself. Point a camera at something you wrote and watch a network from 1998 read it.